@June 18, 2024 9:30 PM (GMT+2)
. . "Artists on a Decade of AI Evolution: An Interview Study of Affordances, Culture, and Artistic Practice with Machine Learning."
@June 18, 2024 9:30 PM (GMT+2)
音楽生成AIが学習データのどの曲から影響を受けたのかを特定する新しい手法を開発
Choi, Woosung, Junghyun Koo, Kin Wai Cheuk, Joan Serrà, Marco A. Martínez-Ramírez, Yukara Ikemiya, Naoki Murata, Yuhta Takida, Wei-Hsiang Liao, and Yuki Mitsufuji. 2025. "Large-Scale Training Data Attribution for Music Generative Models via Unlearning." arXiv preprint arXiv:2506.18312.
@June 18, 2024 9:30 PM (GMT+2)
Mo Yu, Lemao Liu, Junjie Wu, Tsz Ting Chung, Shunchi Zhang, Jiangnan Li, Dit-Yan Yeung, Jie Zhou
The Stochastic Parrot on LLM's Shoulder: A Summative Assessment of Physical Concept Understanding
@June 18, 2024 9:30 PM (GMT+2)
Marwa Abdulhai, Isadora White, Yanming Wan, Ibrahim Qureshi, Joel Leibo, Max Kleiman-Weiner, Natasha Jaques
Abdulhai, Marwa, Isadora White, Yanming Wan, Ibrahim Qureshi, Joel Leibo, Max Kleiman-Weiner, and Natasha Jaques. 2026. "How LLMs Distort Our Written Language." arXiv preprint arXiv:2603.18161.
@June 18, 2024 9:30 PM (GMT+2)
Qiawen Ella Liu, Marina Dubova, Henry Conklin, Takumi Harada, Thomas L. Griffiths
Serendipity by Design: Evaluating the Impact of Cross-domain Mappings on Human and LLM Creativity
@June 18, 2024 9:30 PM (GMT+2)
画像認識モデルで誤ってラベル付けされた画像を提示することで、デザイナーに新しいインスピレーションを与えられることを検証
Liu, Fang, Junyan Lv, Shenglan Cui, Zhilong Luan, Kui Wu, and Tongqing Zhou. 2024. “Smart ‘Error’! Exploring Imperfect AI to Support Creative Ideation.” Proceedings of the ACM on Human-Computer Interaction 8 (CSCW1): 1–28.

2024
生成AIをデザインの過程で使うと、AIのアウトプットに無意識に引っ張られてしまい、アイデアの多様性が奪われてしまう可能性がある
Wadinambiarachchi, Samangi, Ryan M. Kelly, Saumya Pareek, Qiushi Zhou, and Eduardo Velloso. 2024. “The Effects of Generative AI on Design Fixation and Divergent Thinking.” arXiv [Cs.HC]. arXiv. http://arxiv.org/abs/2403.11164.

2024
SunoやUdioで生成した楽曲を識別するためのフレームワーク
Rahman, Md Awsafur, Zaber Ibn Abdul Hakim, Najibul Haque Sarker, Bishmoy Paul, and S. Fattah. 2024. “SONICS: Synthetic or Not -- Identifying Counterfeit Songs,” August. http://arxiv.org/abs/2408.14080.

2024
LLMが生成したテキストを学習に利用→新しい学習データを生成→学習を繰り返した結果… Natureに掲載された論文
Shumailov, Ilia, Zakhar Shumaylov, Yiren Zhao, Nicolas Papernot, Ross Anderson, and Yarin Gal. 2024. “AI Models Collapse When Trained on Recursively Generated Data.” Nature 631 (8022): 755–59.

2024
アートを含まない学習データを学習したAIモデルをベースに、少数のアート作品の画像でLoRAを学習。きちんとそのアーティストの特徴を掴んだ画像が生成された。
Ren, Hui, Joanna Materzynska, Rohit Gandikota, David Bau, and Antonio Torralba. 2024. “Art-Free Generative Models: Art Creation Without Graphic Art Knowledge.” http://arxiv.org/abs/2412.00176.

2019
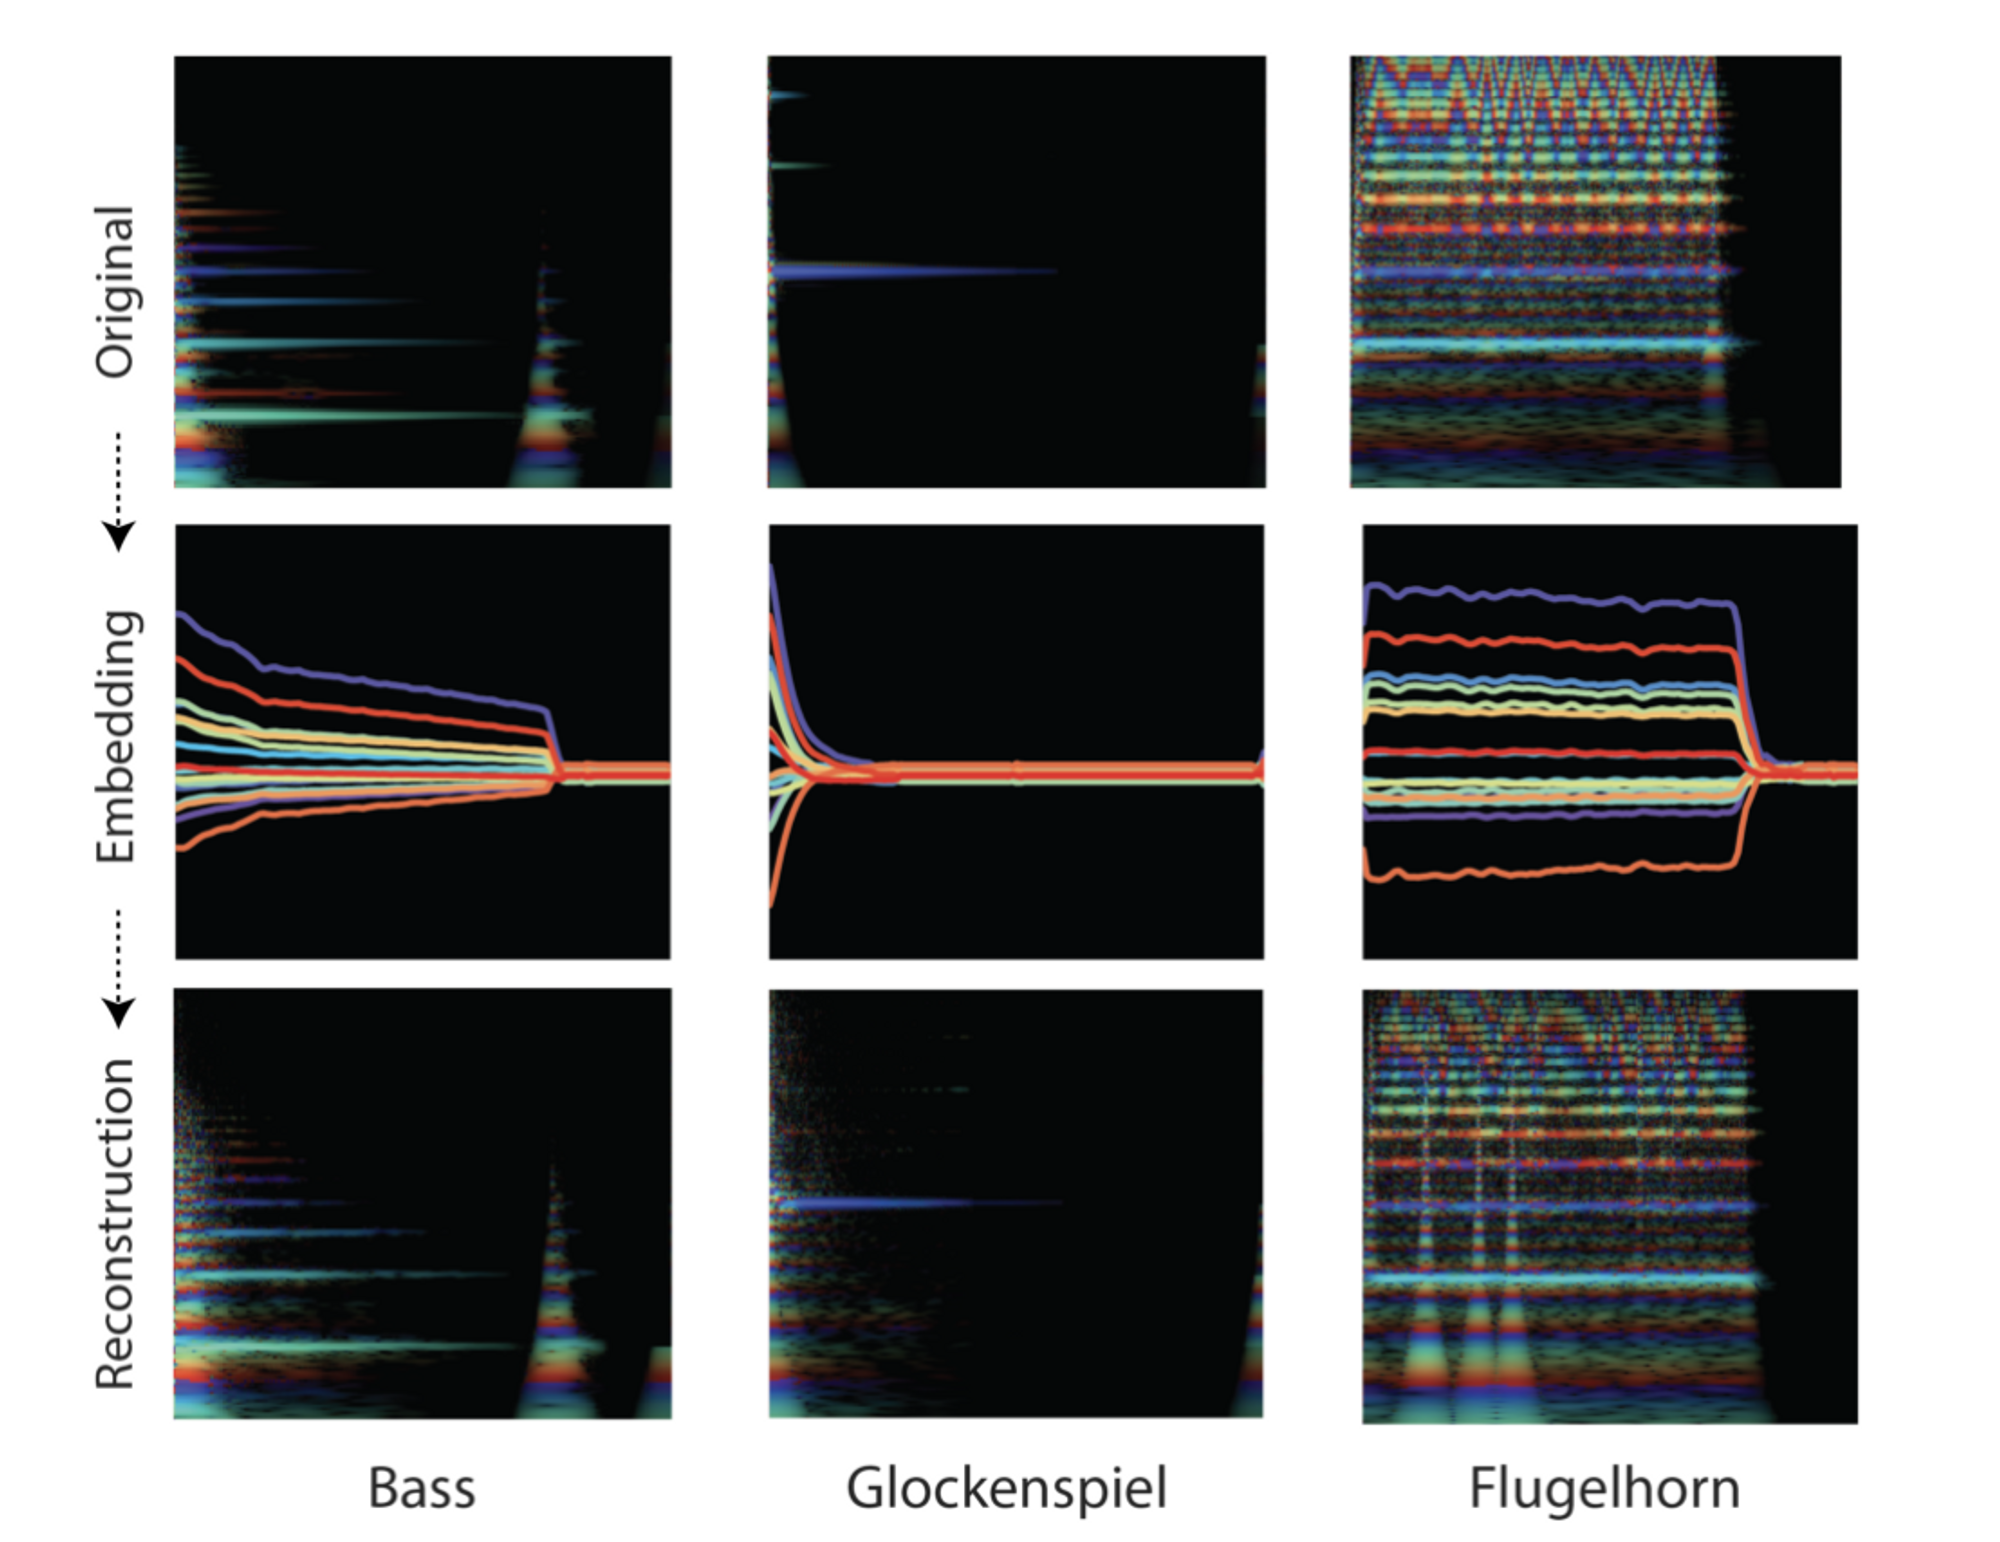
Caillon, Antoine, and Philippe Esling. 2021. “RAVE: A Variational Autoencoder for Fast and High-Quality Neural Audio Synthesis.” arXiv [cs.LG]. arXiv. http://arxiv.org/abs/2111.05011.

2024
ChatGPTの本質を、哲学者のフランクファートが提唱した概念、「ブルシット=ウンコな議論」を通して捉え直す
Hicks, Michael Townsen, James Humphries, and Joe Slater. 2024. “ChatGPT Is Bullshit.” Ethics and Information Technology 26 (2). https://doi.org/10.1007/s10676-024-09775-5.

2023
LLMと複数の音声合成モデルを駆使して、テキストプロンプトからスピーチ、音楽、SEなどを含む音のコンテンツ(ラジオドラマ、ポッドキャストのようなもの)を生成
Liu, Xubo, Zhongkai Zhu, Haohe Liu, Yi Yuan, Meng Cui, Qiushi Huang, Jinhua Liang, et al. 2023. “WavJourney: Compositional Audio Creation with Large Language Models.” arXiv [cs.SD]. arXiv. http://arxiv.org/abs/2307.14335.

2024
音楽生成AIは学習データをコピーしているだけではないか? 学習データと生成されたデータを比較。
Bralios, Dimitrios, Gordon Wichern, François G. Germain, Zexu Pan, Sameer Khurana, Chiori Hori, and Jonathan Le Roux. 2024. “Generation or Replication: Auscultating Audio Latent Diffusion Models.” In ICASSP 2024 - 2024 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), 1156–60. IEEE.

2021
生成モデル(Generative Models)をはじめとするAIモデルの精度が上がる=学習データのパターンをより忠実に再現、再構成できるようになってきた一方で、創造性の観点から言うとそれって学習データものの焼き直しに過ぎないのでは? とう疑問も。 どう適度な逸脱を図るか… が本論文のテーマ。
Broad, Terence, Sebastian Berns, Simon Colton, and Mick Grierson. 2021. “Active Divergence with Generative Deep Learning -- A Survey and Taxonomy.” arXiv [cs.LG]. arXiv. http://arxiv.org/abs/2107.05599.

2023
まだチューリング・テストをクリアしているとは言えなそう… 今、テストを実施する意味とは?
Jones, Cameron, and Benjamin Bergen. 2023. “Does GPT-4 Pass the Turing Test?” arXiv [cs.AI]. arXiv. http://arxiv.org/abs/2310.20216.

2023
アーティストのスタイルが勝手に模倣されることを防ぐ Adversarial Example
Shan, Shawn, Jenna Cryan, Emily Wenger, Haitao Zheng, Rana Hanocka, and Ben Y. Zhao. 2023. “GLAZE: Protecting Artists from Style Mimicry by Text-to-Image Models.” arXiv [cs.CR]. arXiv. http://arxiv.org/abs/2302.04222.

2023
Liu, Haohe, Zehua Chen, Yi Yuan, Xinhao Mei, Xubo Liu, Danilo Mandic, Wenwu Wang, and Mark D. Plumbley. 2023. “AudioLDM: Text-to-Audio Generation with Latent Diffusion Models.” arXiv [cs.SD] . arXiv. http://arxiv.org/abs/2301.12503.
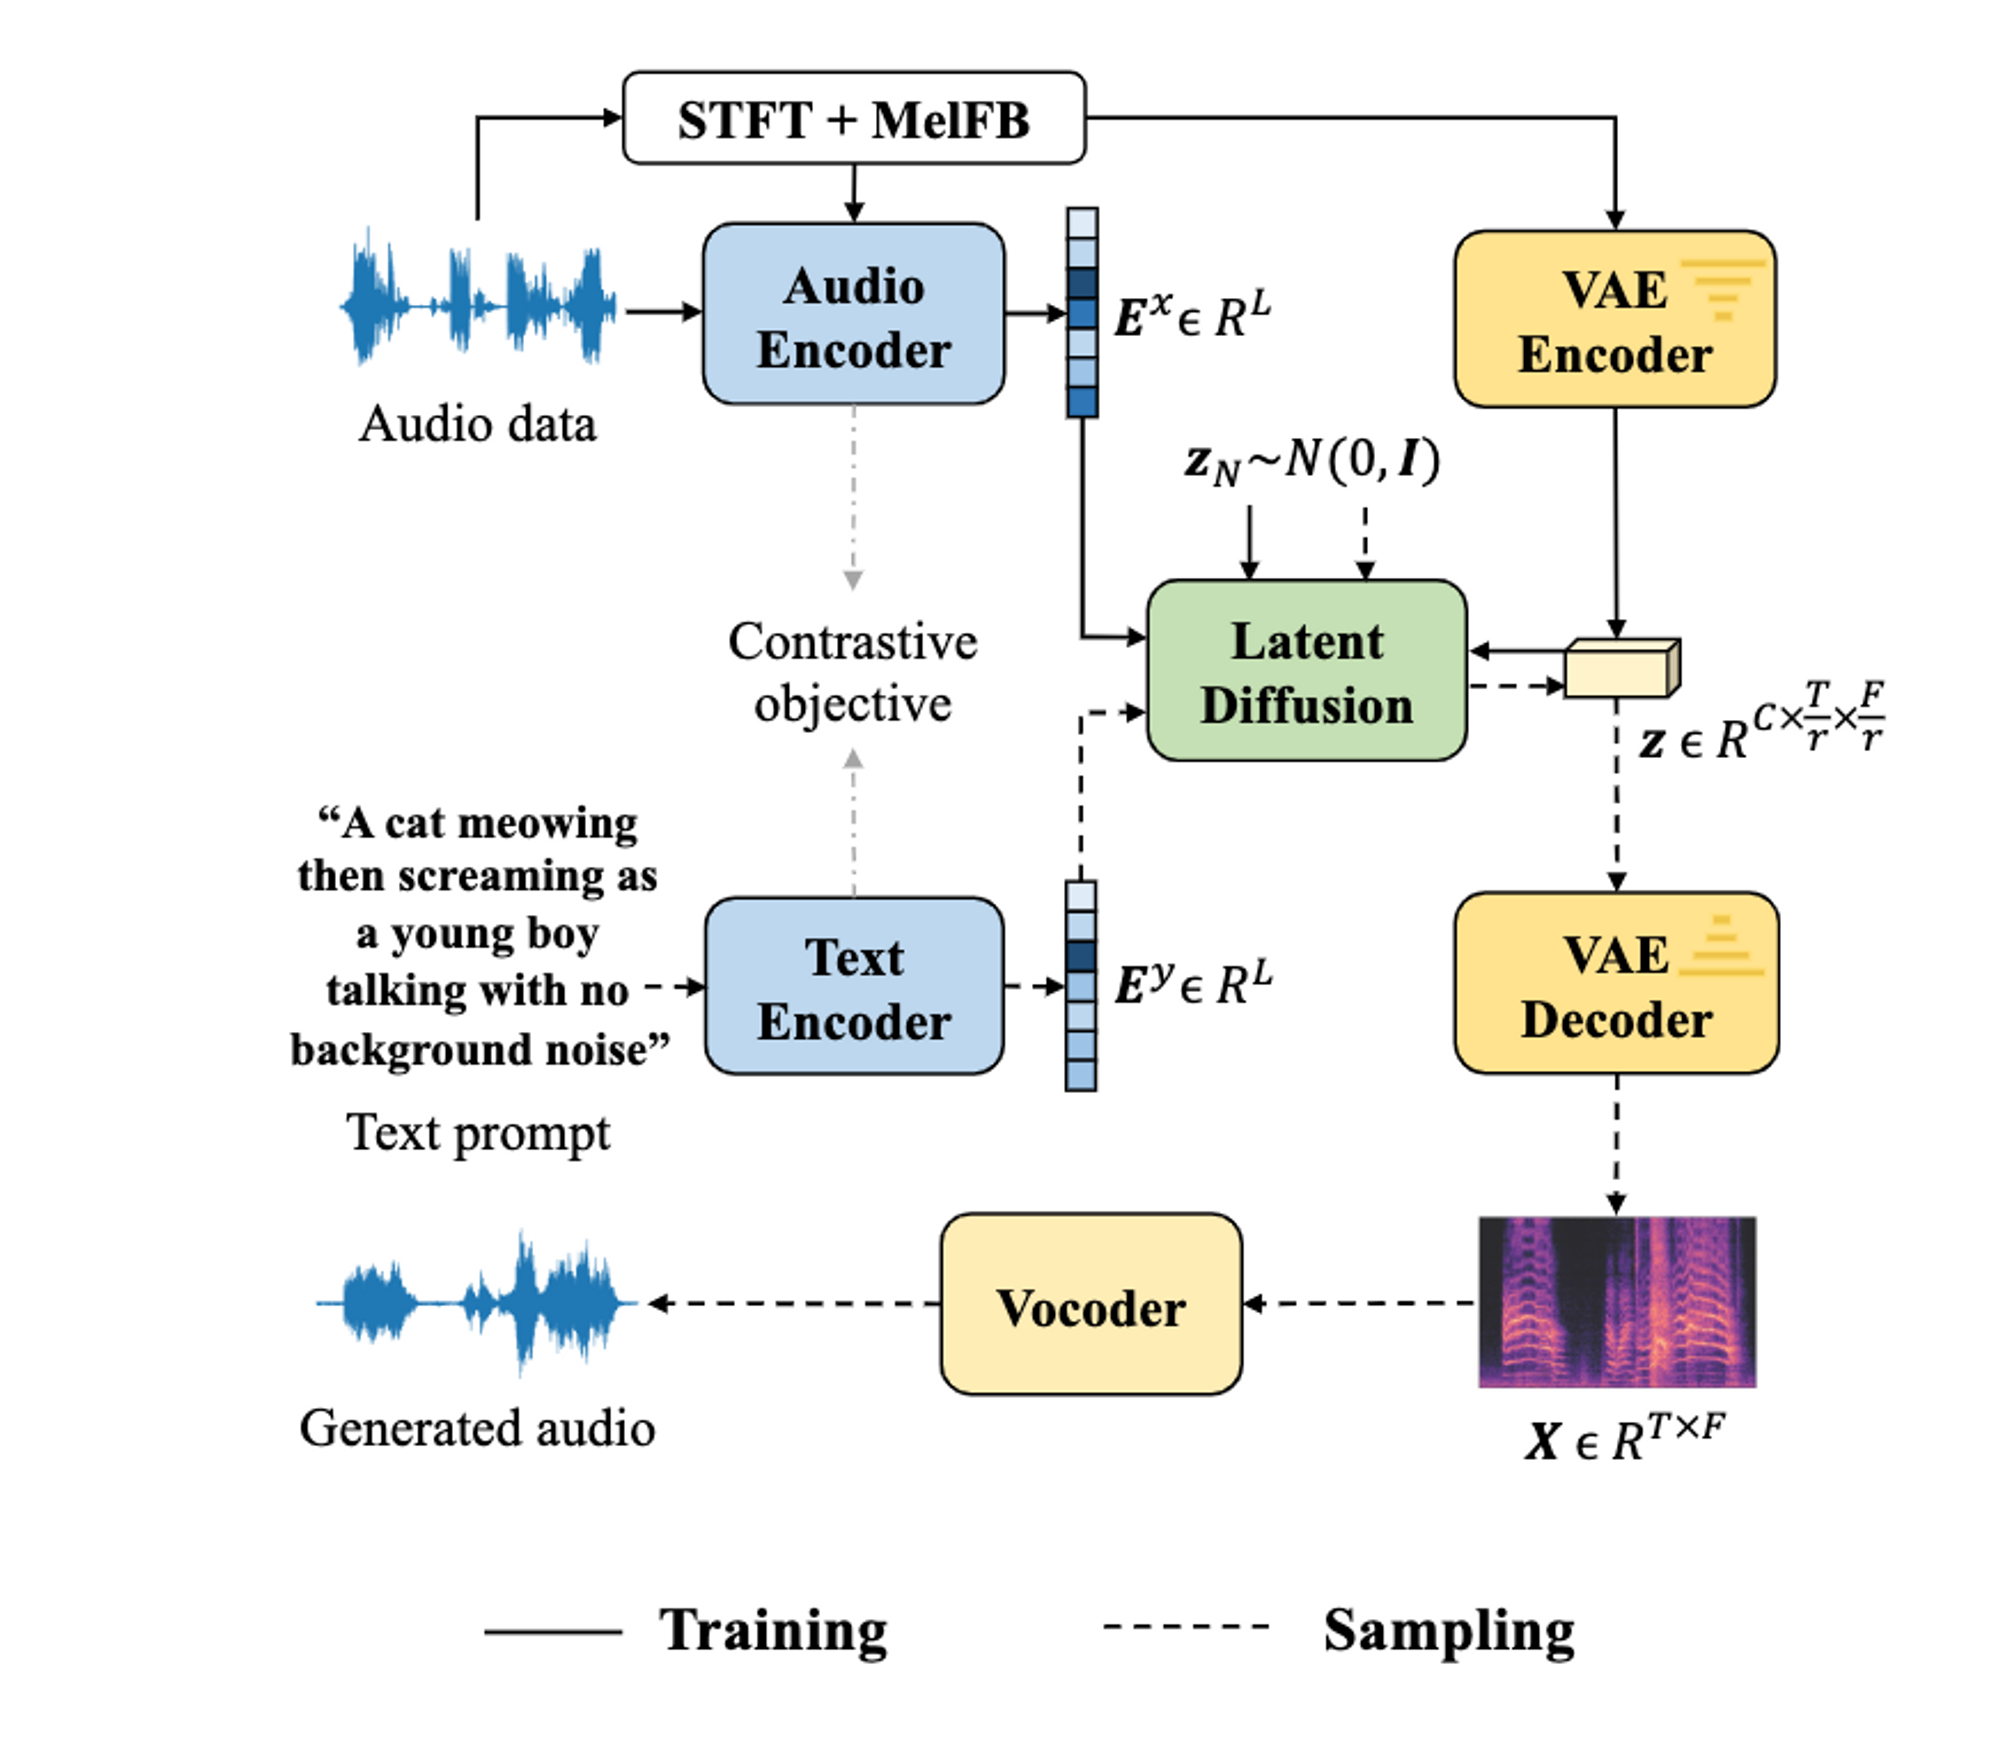
CLAPを用いることでText-to-AudioのSOTAを達成。オープンソース化されていて、すぐに試せるオンラインデモもあり!
2023
音源分離技術を使ってボーカルとそれに付随する伴奏を抽出。その関係を学習。Ground Truth (元々の曲に入ってた伴奏)には流石に劣るがそれに匹敵するクオリティの曲を生成できるようになった。
Donahue, Chris, Antoine Caillon, Adam Roberts, Ethan Manilow, Philippe Esling, Andrea Agostinelli, Mauro Verzetti, et al. 2023. “SingSong: Generating Musical Accompaniments from Singing.” arXiv [cs.SD] . arXiv. http://arxiv.org/abs/2301.12662.

2023
Latent Diffusionのアーキテクチャを利用して、テキストから音楽を生成するモデル
Schneider, Flavio, Zhijing Jin, and Bernhard Schölkopf. 2023. “Moûsai: Text-to-Music Generation with Long-Context Latent Diffusion.” arXiv [cs.CL] . arXiv. http://arxiv.org/abs/2301.11757.

2023
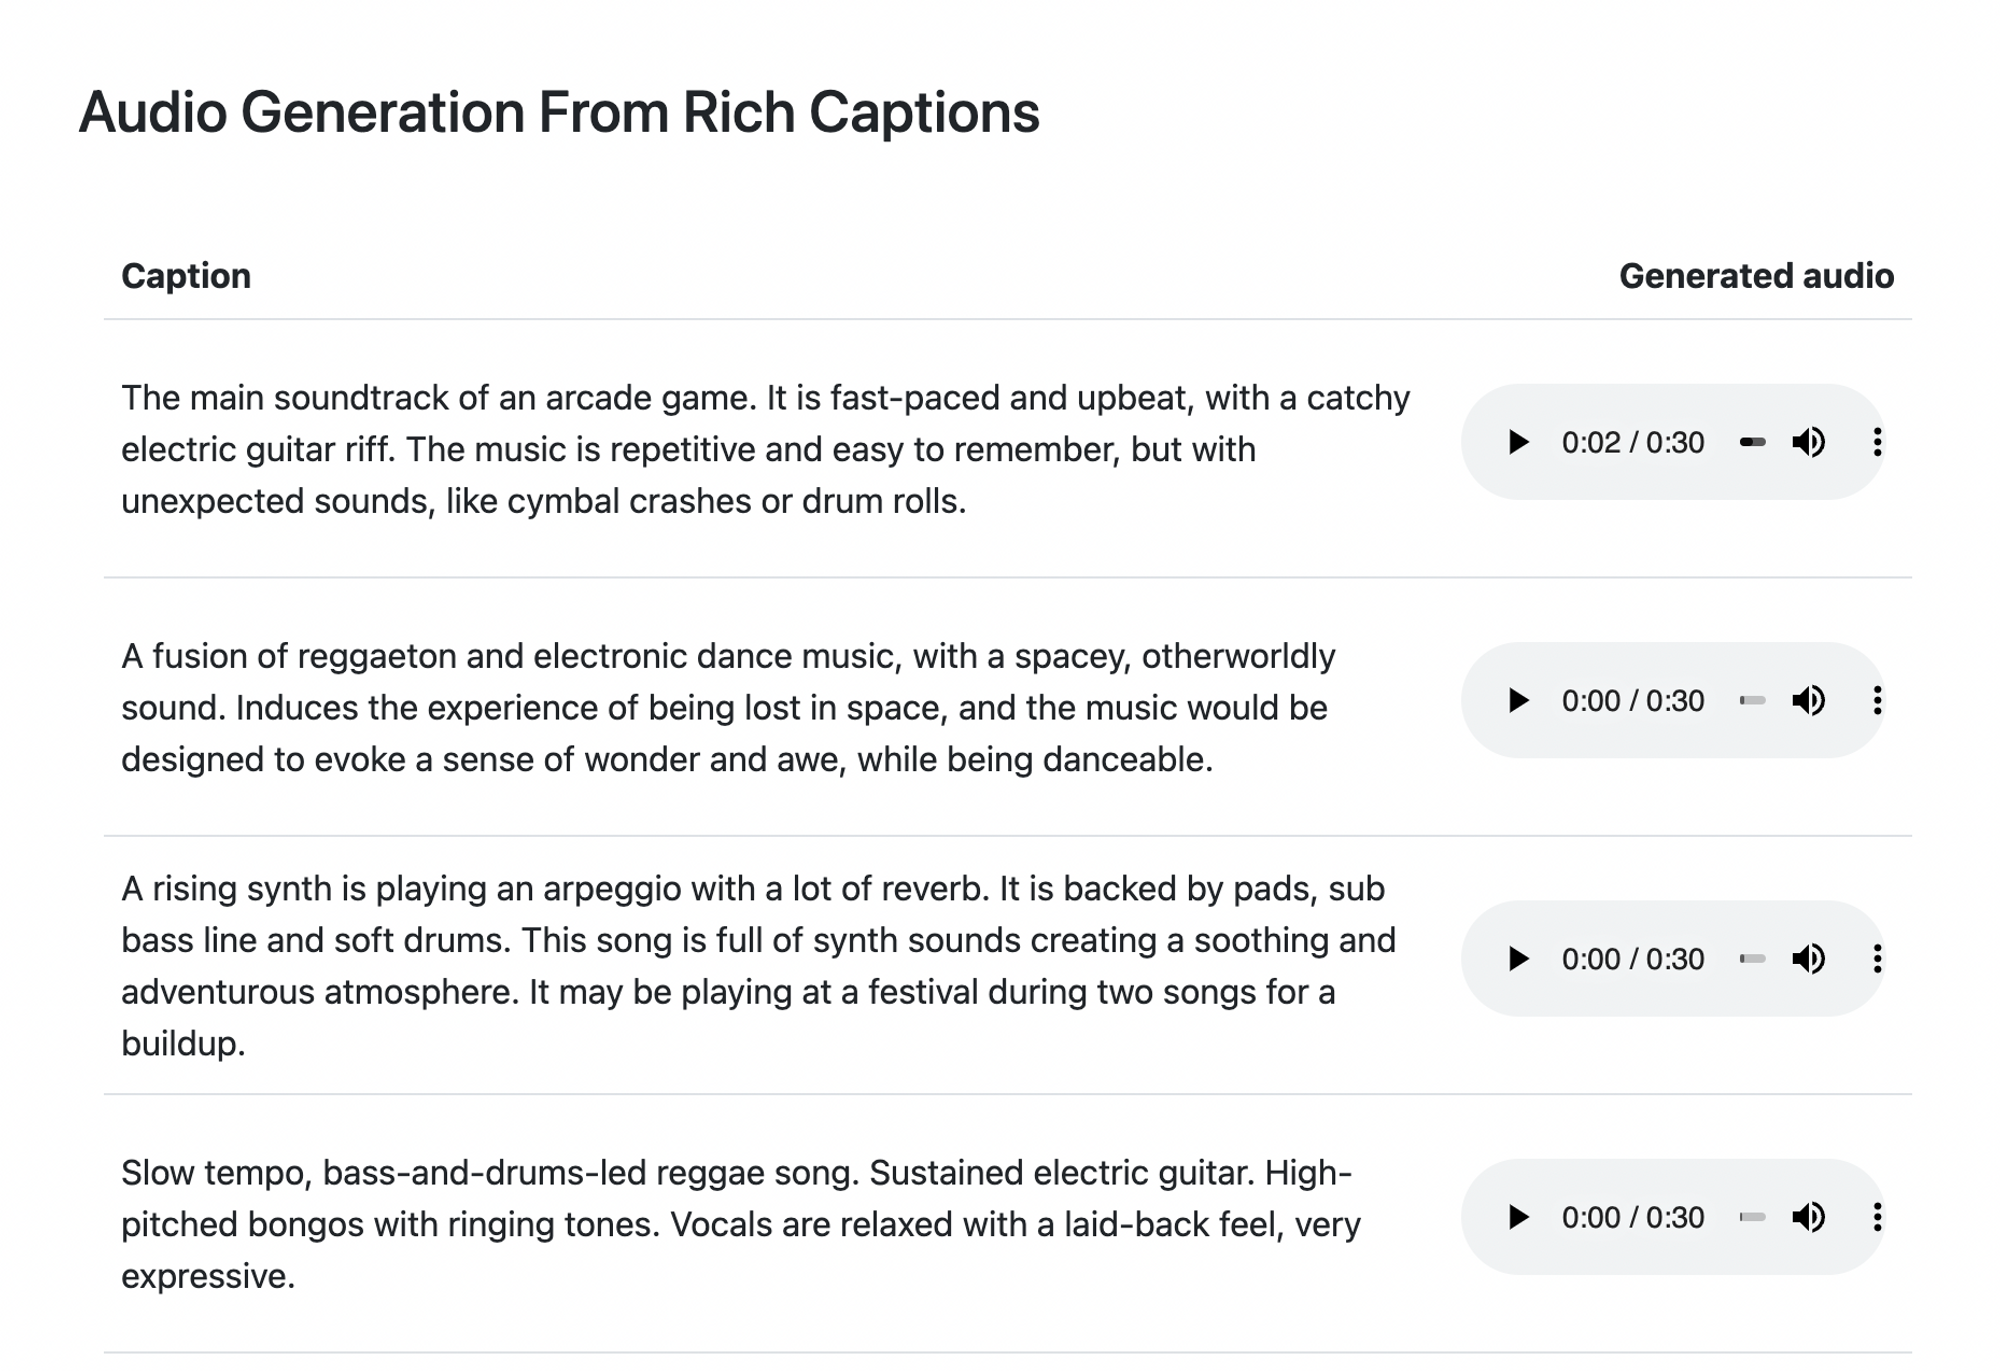
“a calming violin melody backed by a distorted guitar riff” といったテキストから音楽がサウンドファイルとして生成される. Stable Diffusionの音楽版
Agostinelli, Andrea, Timo I. Denk, Zalán Borsos, Jesse Engel, Mauro Verzetti, Antoine Caillon, Qingqing Huang, et al. 2023. “MusicLM: Generating Music From Text.” arXiv [cs.SD] . arXiv. http://arxiv.org/abs/2301.11325.
2022
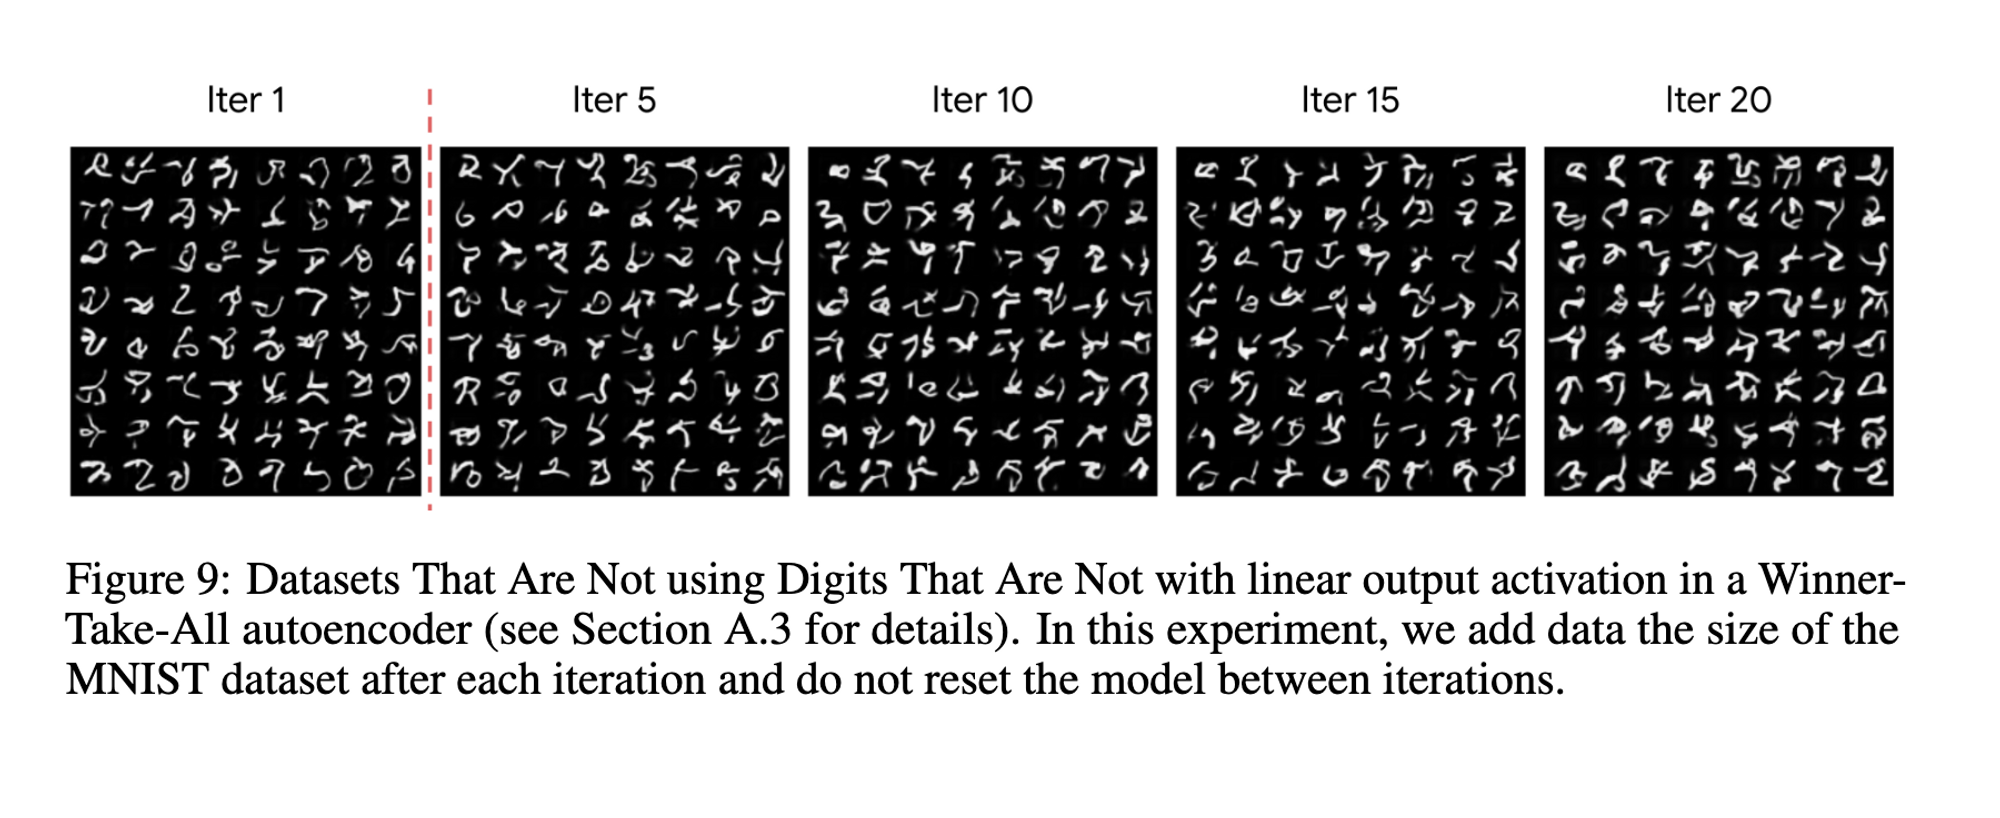
データセットの模倣ではない、新奇性の高い出力を生成AIを用いて実現するために、生成した画像をデータセットに追加していくことを繰り返す
Wu, Yusong, Kyle Kastner, Tim Cooijmans, Cheng-Zhi Anna Huang, and Aaron Courville. n.d. “Datasets That Are Not: Evolving Novelty Through Sparsity and Iterated Learning.”
2018
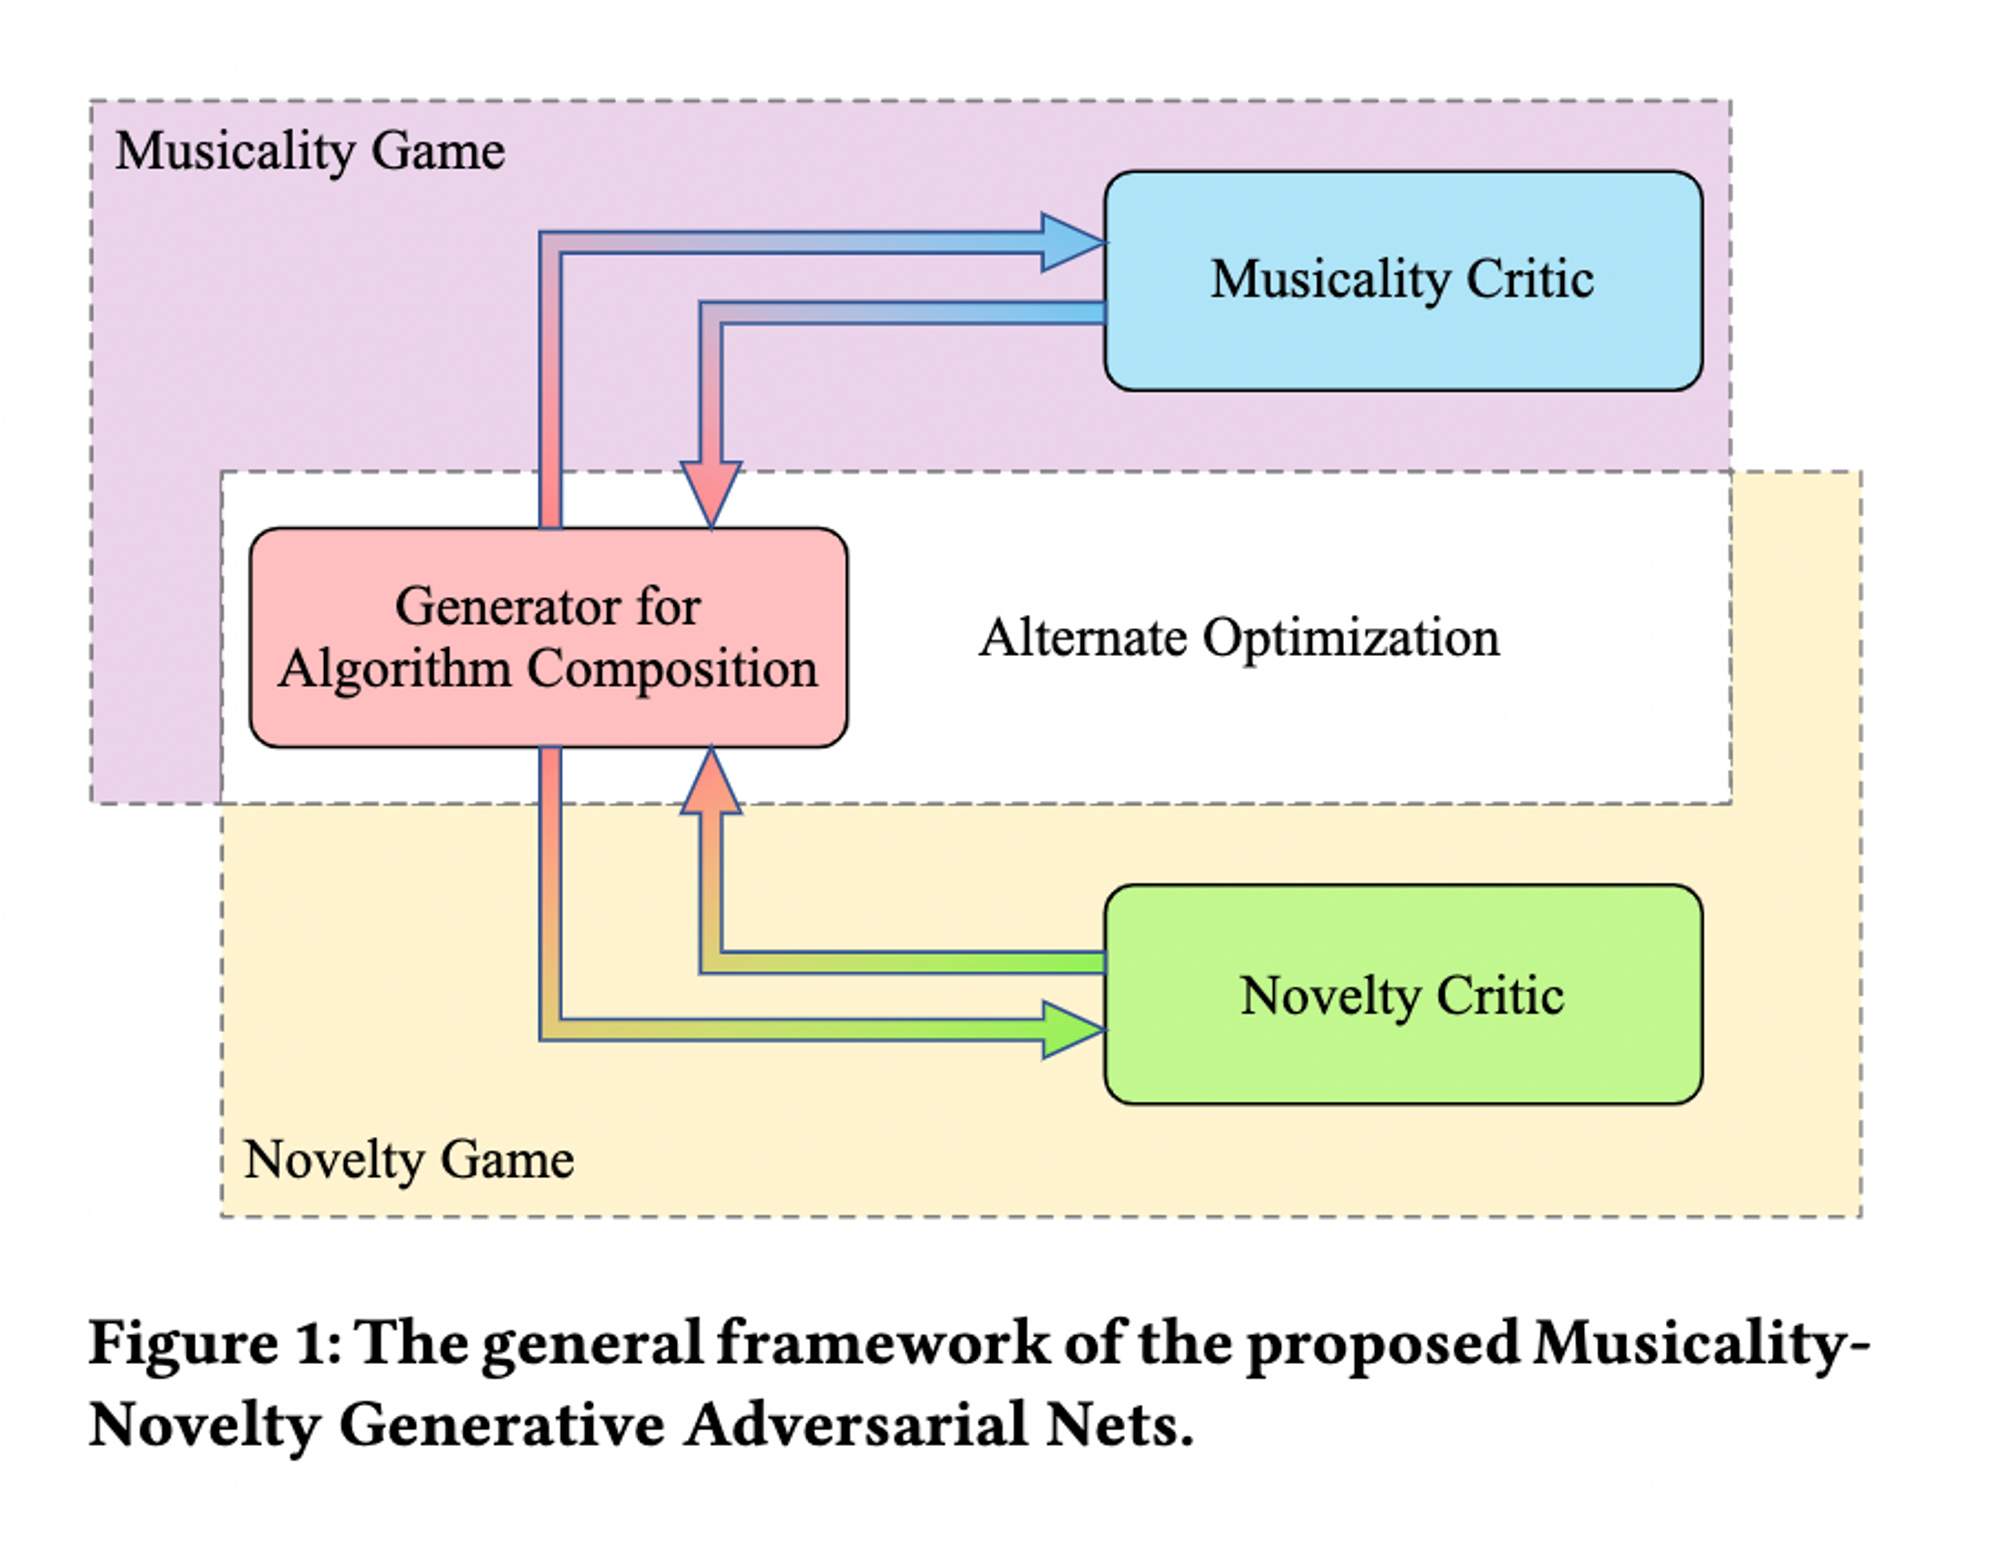
人真似ではない新しい音楽をAIで生成しようとする野心的な研究
Chen, Gong, Yan Liu, Sheng-Hua Zhong, and Xiang Zhang. 2018. “Musicality-Novelty Generative Adversarial Nets for Algorithmic Composition.” In Proceedings of the 26th ACM International Conference on Multimedia , 1607–15. MM ’18. New York, NY, USA: Association for Computing Machinery.

2021
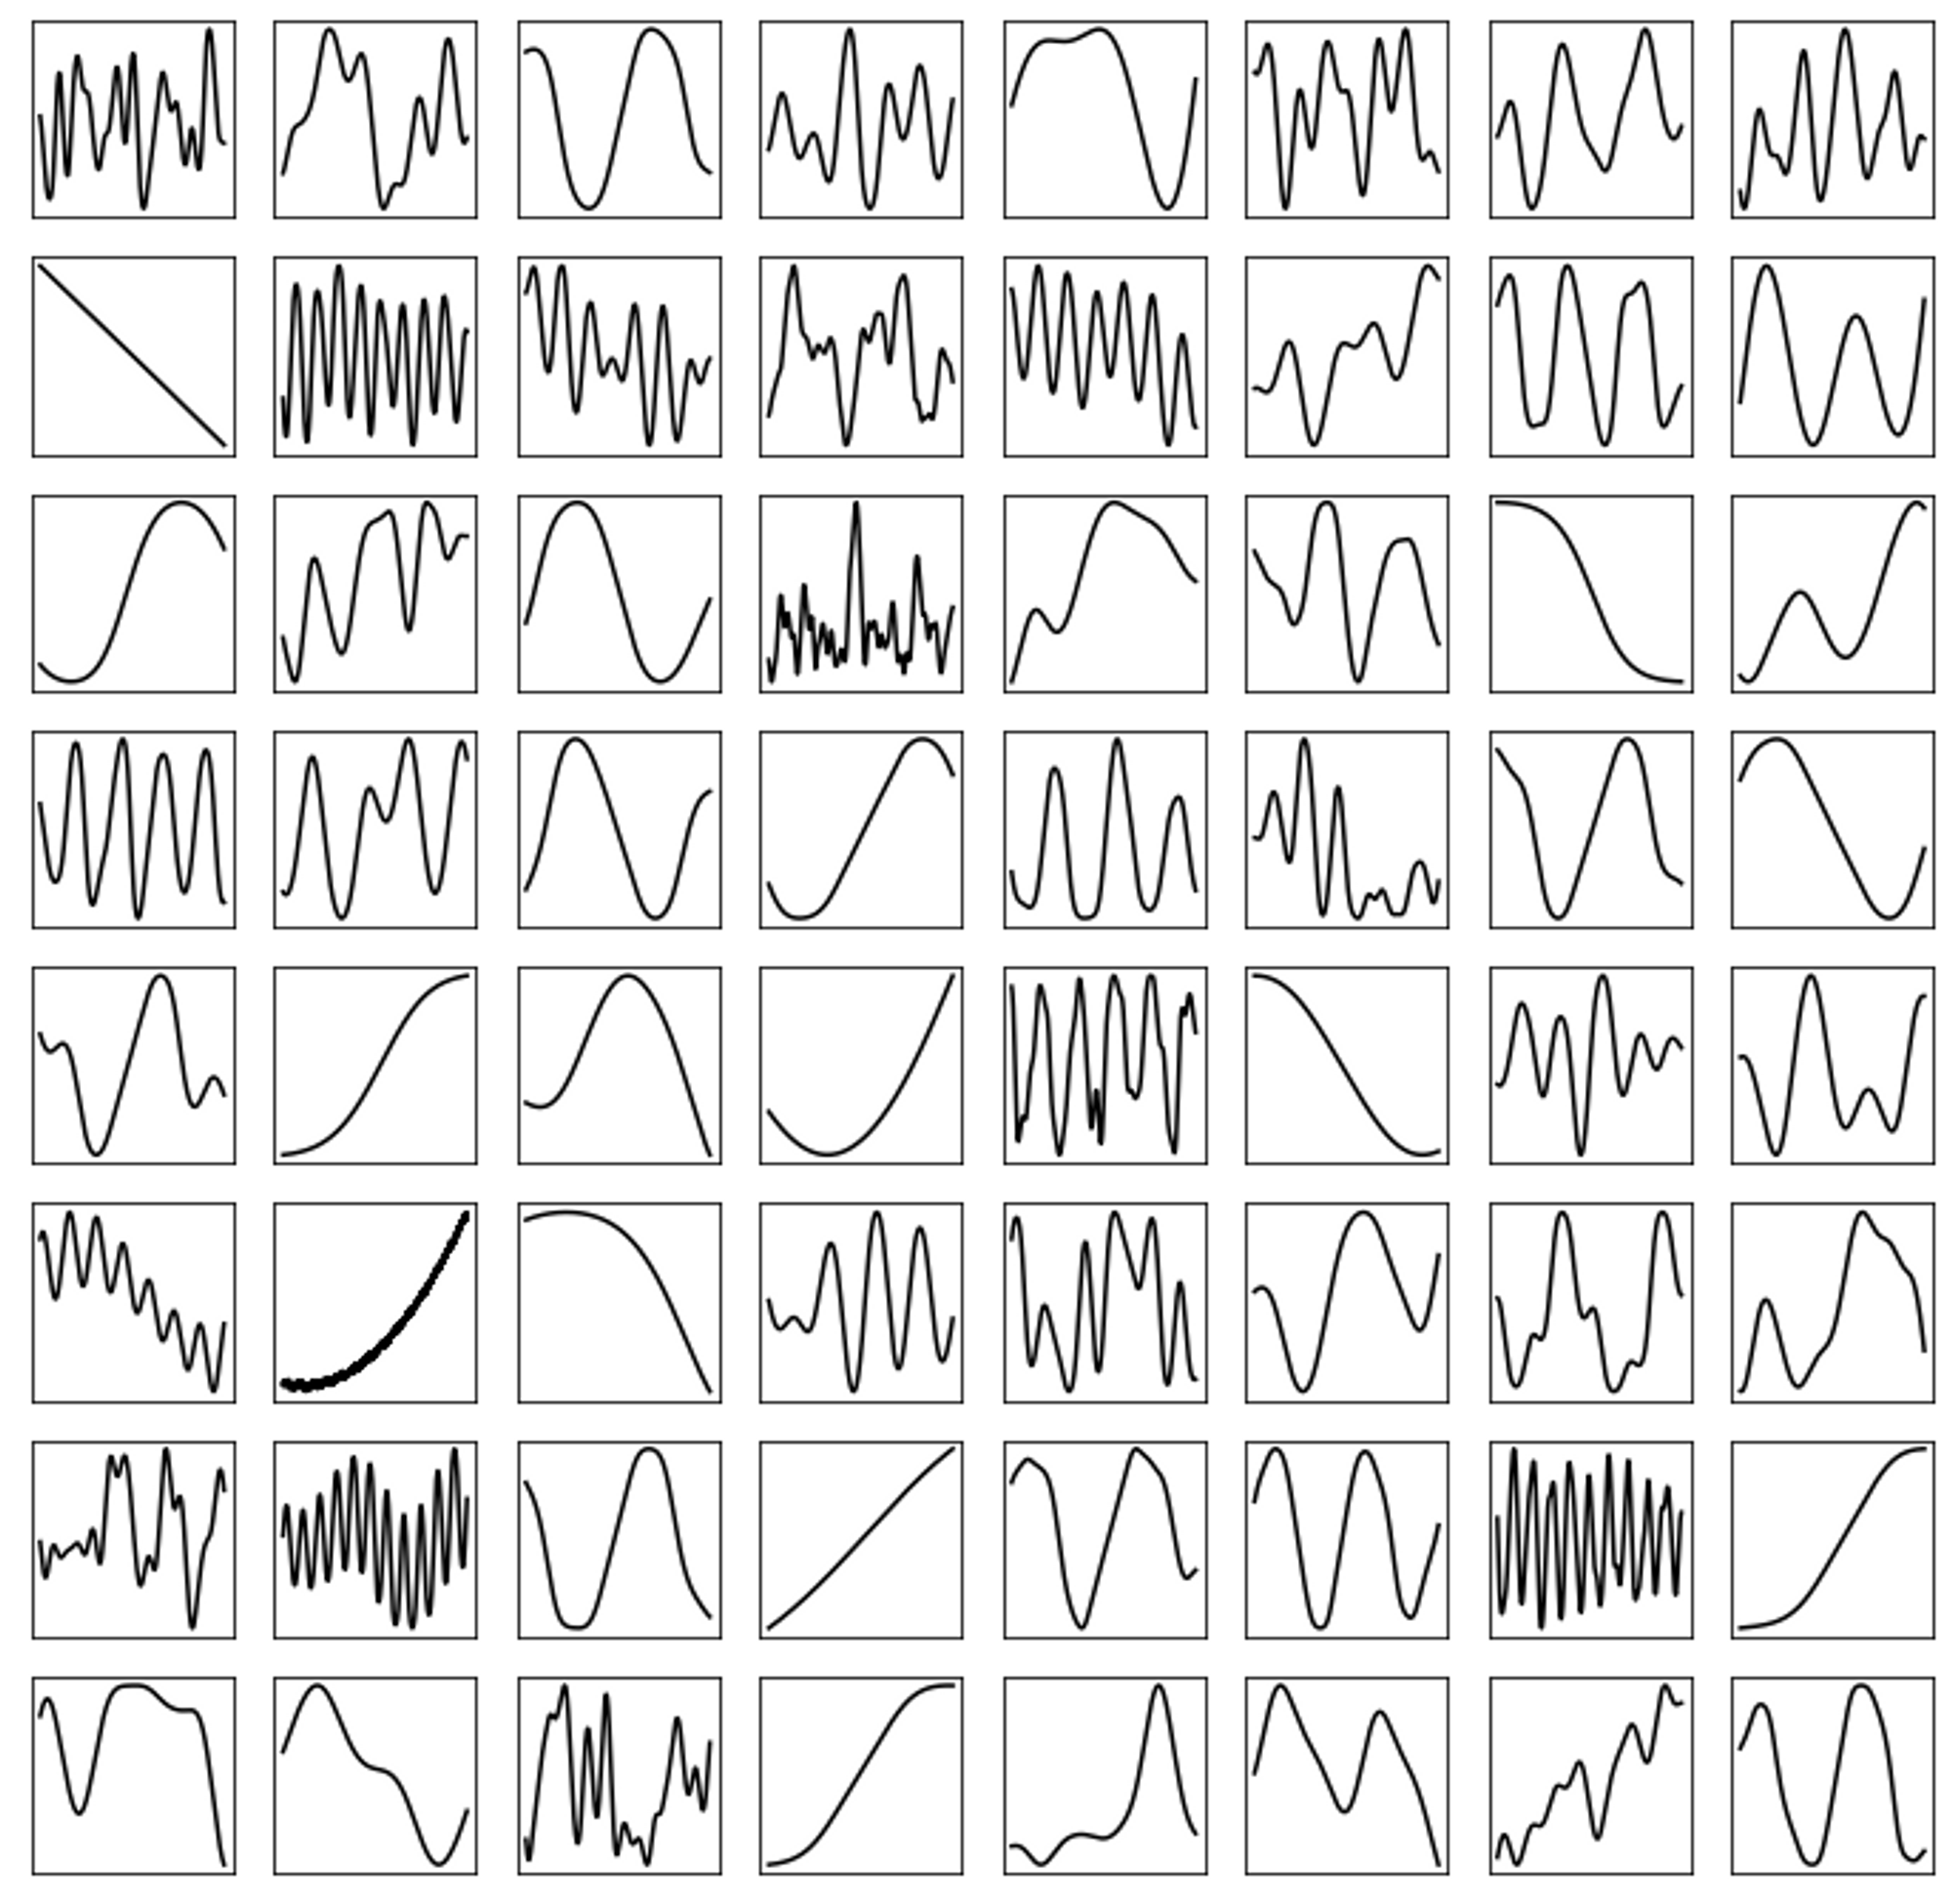
CPUでもサクサク動くのがポイント!
Hayes, B., Saitis, C., & Fazekas, G. (2021). Neural Waveshaping Synthesis.
2021
画像とテキストがどれくらいマッチしているかを定量化するCLIPモデルを用いて、要素画像の配置を最適化。入力されたテキストにあったコラージュ画像を生成するシステム
CLIP-guided collage image optimization using Evolutionary Strategy

2021
CLIP+VQ-GANの仕組みを活用
Botto Project

2019
X線写真をコンテンツ画像に、同時代の同じ作家の絵をスタイル画像としてスタイルトランスファーをかける。美術史家などからその手法に対して強い批判も上がっている。
Bourached, A., & Cann, G. H. (2019). Raiders of the Lost Art. CrossTalk, 22(7–8), 35. https://doi.org/10.1525/9780520914957-028

2021
CLIPからオーディオ表現を抽出する手法であるWav2CLIPを提案。オーディオ分類・検索タスクで良好な結果を残す

2021
テキストと画像がどのくらいマッチしているかを定量化するモデル OpenAI CLIPを評価関数に用いて、進化戦略ESによって生成した抽象画
YINGTAO TIAN, DAVID HA. Modern Evolution Strategies for Creativity: Fitting Concrete Images and Abstract Concepts (2021)

2021
顔をディープフェイク技術で動かし、リップシンクした音声を追加することで作ったDeepfake動画のデータセット。ディープフェイクへの対抗策の研究が目的。
FakeAVCeleb: A Novel Audio-Video Multimodal Deepfake Dataset, Hasam Khalid, Shahroz Tariq, Minha Kim, Simon S. Woo (2021)

2021
OpenAIの言語モデルGPT3を用いた即興劇。ロンドンの劇場での公演。
AI by Jennifer Tang

2021
なんと総時間は約126年分!! データセットを生成するためにpytorch上に実装された、GPUに最適化されたモジュラーシンセ torchsynthも合わせて公開。
Turian, J., Shier, J., Tzanetakis, G., McNally, K., & Henry, M. (2021). One Billion Audio Sounds from GPU-enabled Modular Synthesis.

2021
画像とテキストの関連性の高さを判定するモデルCLIPを用いて、生成される画像を最適化 → テキストの入力にあった画像が生成
OpenAI CLIP + Image Generation Models = CLIP art

2021
顔認識とオブジェクト認識を組み合わせて、議会中に電話をいじっている議員を摘発
The Flemish Scrollers, Dries Depoorter (2021)

2020
現代の音楽制作過程で重要なループの組み合わせ。たくさんあるループ間の相性を判定して、適切なループの組み合わせをレコメンドする仕組み。
Chen, B.-Y., Smith, J. B. L. and Yang, Y.-H. (2020) ‘Neural Loop Combiner: Neural Network Models for Assessing the Compatibility of Loops’.

2020
AIや機械学習が社会で用いられる場合、時にそれが市民を搾取するかたちで使われることがある。そうしたAIの利用の実例を取り上げてカタログ化するDigital Activism。
Algorithms of Late-Capitalism (2020-)

2021
Google Magentaチームの最新のプロジェクト。2020年に発表した DDSP: Differentiable Digital Signal Processing を使って、絵筆のストロークを楽器音に変えている。筆で描くように音を奏でることができる。
Paint with Music - Google Magenta

2020
AI音楽ツールに対する意識調査を117名に対してオンラインで行った。結論からいうと... AIツールはほとんど使われていない。AIツールに対してポジティブな人も、現状ではなく未来の可能性にひかれている。
Knotts, S., & Collins, N. (2020). A survey on the uptake of Music AI Software. Proceedings of the International Conference on New Interfaces for Musical Expression, 594–600.
2020
GANやAutoEncoderが使われている。2021年のアルスエレクトロニカ Digital Musics & Sound Art 部門のゴールデンニカ(最優秀賞)。
Alexander Schubert - Convergence (2020)
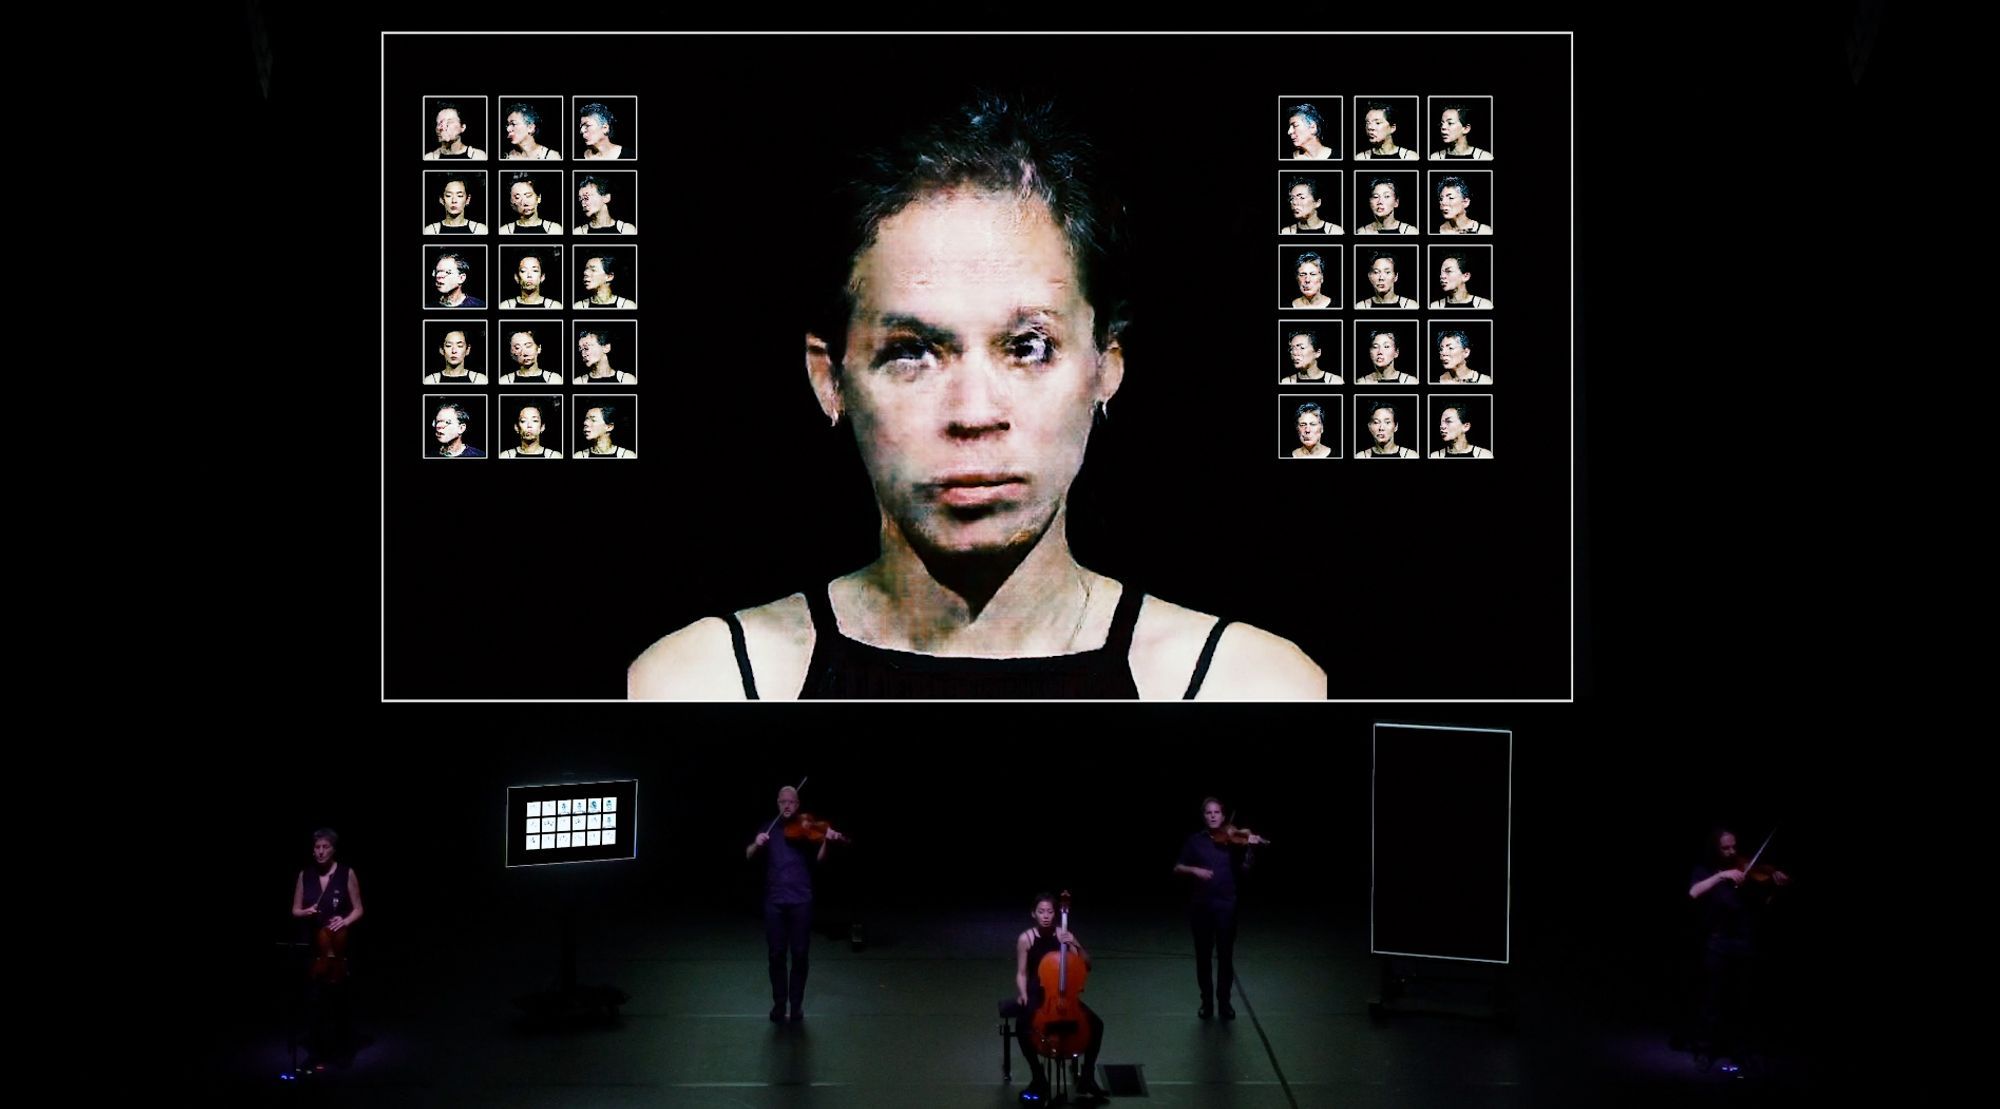
2021
バイアスやプライバシーへの配慮から、人を対象にしたデータセットを集めることが難しくなっている。そこでGANなどを使って、適切なデータセットを人工的に作り出す仕組みを提供するスタートアップが登場した。
-

2019
GPT-2などの言語モデルについて、その精度ではなく、学習時に消費している電力及び、二酸化炭素の放出量についてまとめた。この研究の試算では、例えばTransformer の学習に、一般的な自動車のライフサイクルの約5台分、アメリカ人約17人の一年分に相当するカーボンフットプリントがあることがわかった。
Emma Strubell, Ananya Ganesh, Andrew McCallum (2019)

2020
少量の学習データでも効率的に学習できるように、最近のダンスミュージックの特徴を生かしたアーキテクチャを採用
Vigliensoni, G., Mccallum, L., & Fiebrink, R. (2020). Creating Latent Spaces for Modern Music Genre Rhythms Using Minimal Training Data. Proc. ICCC 2020.

2021
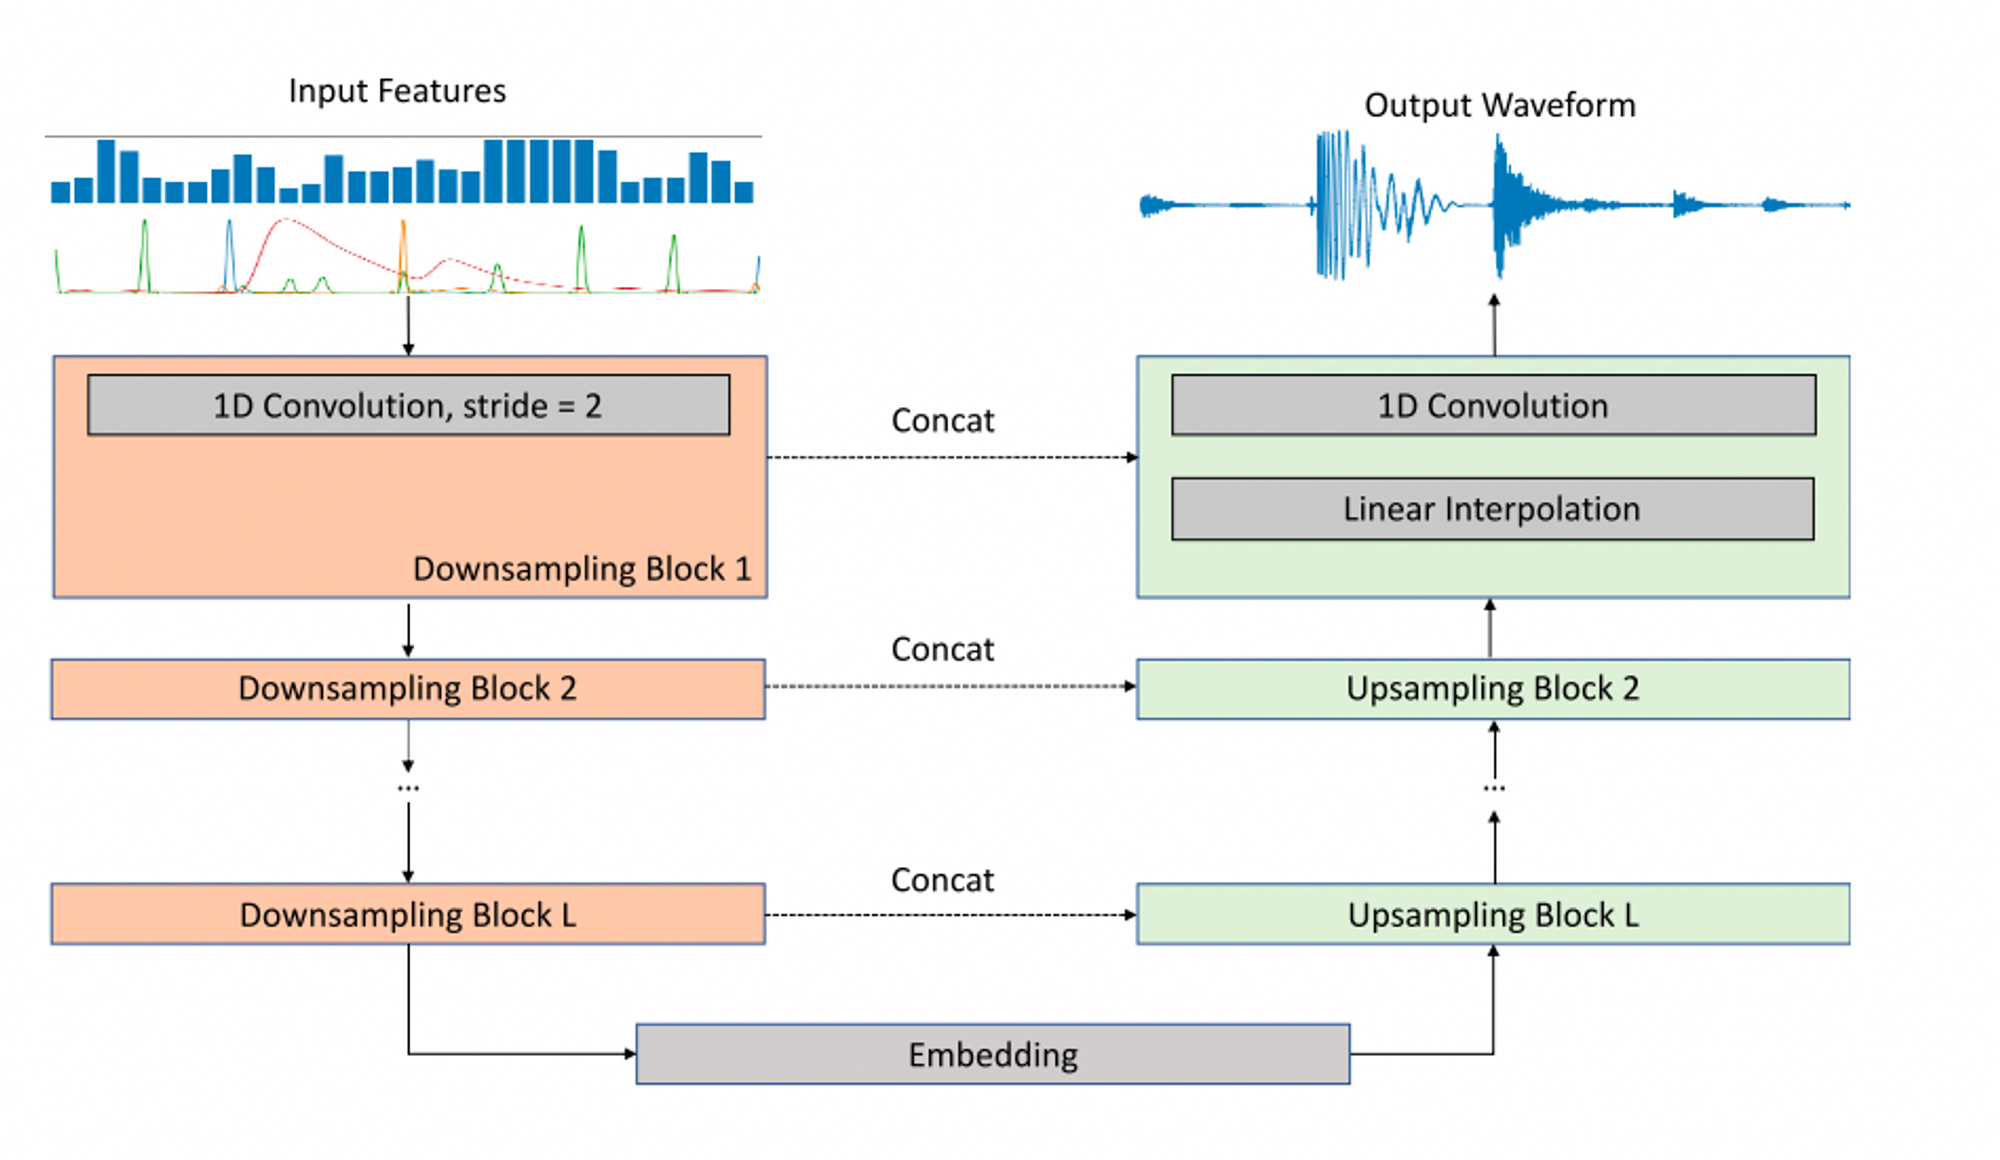
音源分離のモデルで提案されたWave-U-Netのアーキテクチャを用いて、ドラムループをまるごと生成する仕組み
Chandna, P., Ramires, A., Serra, X., & Gómez, E. (2021). LoopNet: Musical Loop Synthesis Conditioned On Intuitive Musical Parameters.
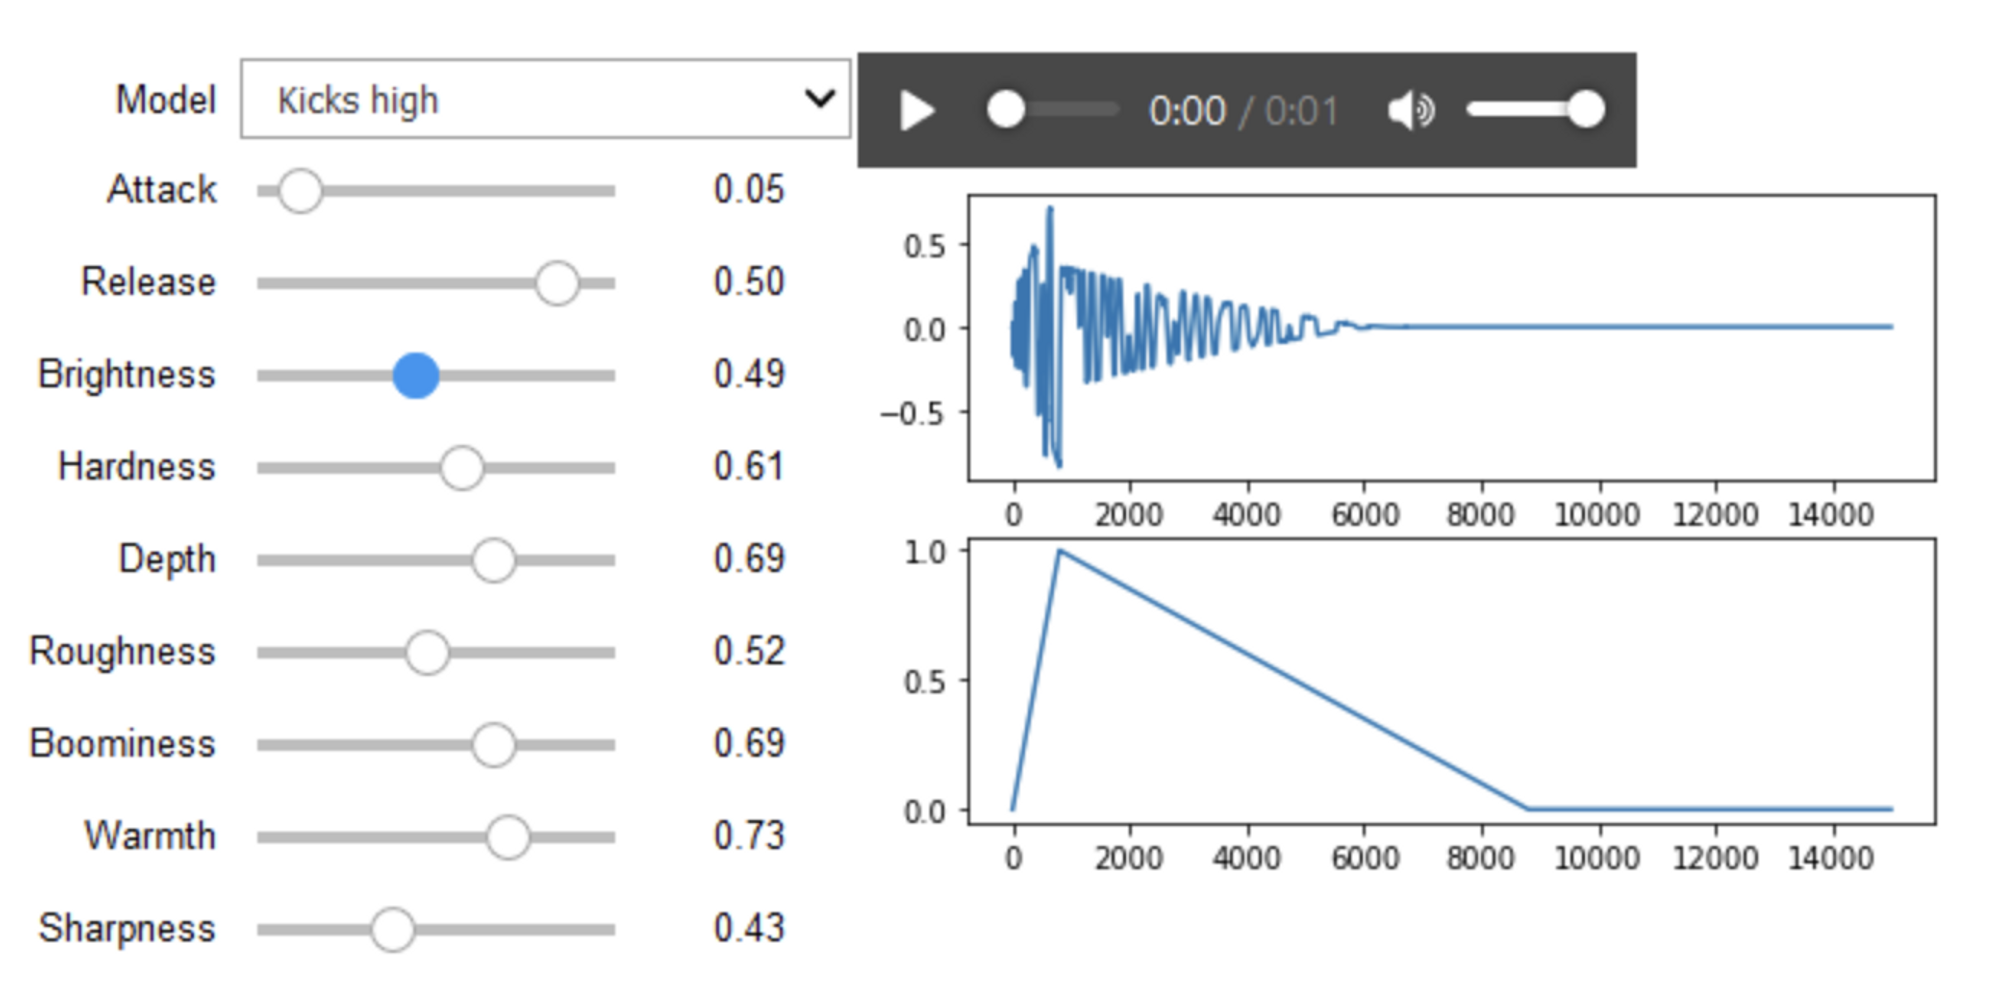
2019
Ramires, A., Chandna, P., Favory, X., Gómez, E., & Serra, X. (2019). Neural Percussive Synthesis Parameterised by High-Level Timbral Features. ICASSP, IEEE International Conference on Acoustics, Speech and Signal Processing - Proceedings, 2020-May, 786–790. Retrieved from http://arxiv.org/abs/1911.11853
2021
400万人の人の2億6000万枚の顔写真のデータセットと、ゴミデータを取り除いた200万人/4200万枚の顔写真のデータセットの二種類を提供
Zhu, Z., Huang, G., Deng, J., Ye, Y., Huang, J., Chen, X., … Zhou, J. (2021). WebFace260M: A Benchmark Unveiling the Power of Million-Scale Deep Face Recognition

2020
世界8都市の街中で撮られた動画から顔を抜き出してCNNを用いた感情推定モデルで解析。都市ごとの有意な差は見当たらないという結果に。
Ozakar, R., Gazanfer, R. E., & Sinan Hanay, Y. (2020, November 25). Measuring happiness around the World through artificial intelligence

2021
リズムパターンのデータセットもあわせて公開。
Tikhonov, A., & Yamshchikov, I. (2021, July 13). Artificial Neural Networks Jamming on the Beat. 37–44. https://doi.org/10.5220/0010461200370044

2019
2019年のNIMEで発表された論文。最新の言語モデル(seq-to-seq model)の知見を利用してドラムトラックの音声ファイルからそれにあったベースラインを生成してくれる。
Behzad Haki, & Jorda, S. (2019). A Bassline Generation System Based on Sequence-to-Sequence Learning. Proceedings of the International Conference on New Interfaces for Musical Expression, 204–209.

2017
WaveNetの仕組みを使ったAutoencoderで、楽器の音の時間方向の変化も含めて、潜在空間にマッピング → 潜在ベクトルから楽器の音を合成する。この研究で使った多数の楽器の音を集めたデータセット NSynth を合わせて公開。
Engel, J. et al. (2017) ‘Neural Audio Synthesis of Musical Notes with WaveNet Autoencoders’. Available